Native linguists performing complex text annotation and named entity recognition to eliminate training data noise | Travod

AI data annotation services

Our global linguist network delivers annotation quality, cultural accuracy, and domain expertise across 100+ languages for NLP, speech, vision, and multimodal AI systems.

Speech and audio annotation capturing regional accents and conversational patterns for voice AI training | Travod

The quality gap that determines model performance

Generic crowdsourced annotation produces inconsistent labels, missed nuances, and cultural blind spots that surface as accuracy problems in production. The gap between benchmark performance and real-world deployment often traces back to training data quality.

Our annotators are the same linguists we deploy for professional translation: native speakers with verified proficiency, subject matter backgrounds, and training in annotation methodology. They bring linguistic intuition to labeling decisions, not just task completion. For organizations building AI that must work across languages and markets, this expertise directly affects whether models perform or disappoint.
Computer vision image labeling and semantic segmentation adapted for localized market contexts | Travod

Text annotation for NLP systems

Named entity recognition, sentiment analysis, intent classification, text categorization. These tasks require annotators who master how language actually works in context. 
Our linguists catch the ambiguities, implicit meanings, and cultural references that determine whether labels reflect reality or introduce noise into your training data.
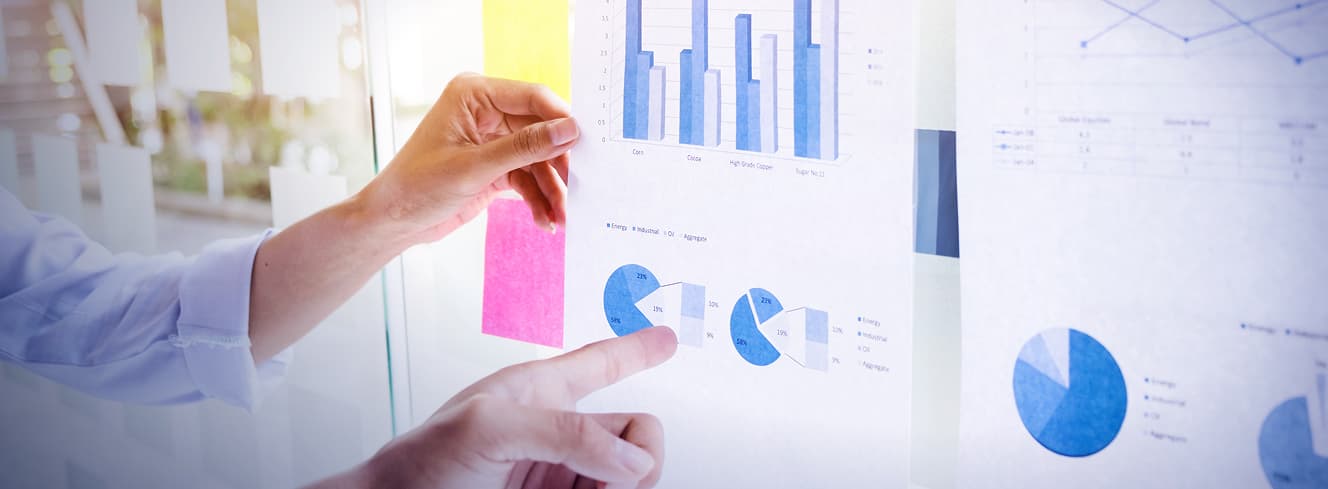
Strategic market expansion data preparation identifying high-opportunity regions through localization insight | Travod

Speech and audio annotation

Our native speakers familiar with regional accents, conversational patterns, and linguistic conventions produce cleaner transcripts and more accurate labels than annotators working in their second language. 
For speech recognition and voice AI, this precision compounds across millions of training examples. Small improvements in annotation accuracy translate to measurable gains in model performance.
Structuring high-precision data annotation metrics using strict inter-annotator agreement standards | Travod

Image and video annotation

Object detection, semantic segmentation, action recognition, scene classification. Visual annotation benefits from domain context and cultural awareness. 
What counts as appropriate, what objects are called in different markets, how actions are interpreted across cultures. Our annotators bring this context to labeling decisions.
Mitigating machine learning performance drops caused by crowdsourced dataset labeling errors | Travod

Market expansion strategies

Case studies from successful market entries reveal how the right company combines market research with localisation expertise to identify high-opportunity regions. 
This strategic decision - making process ensures resources focus on markets with the highest ROI potential.
Dedicated domain-specific labeling pipelines matching technical and medical training sets with specialized subject experts | Travod

Annotation standards that scale

Annotation quality requires more than good intentions. We implement structured methodology: annotator training and certification, detailed guidelines with edge case documentation, ongoing calibration sessions, inter-annotator agreement measurement, systematic adjudication for disagreements, and regular quality audits.

Quality metrics are tracked throughout production and reported with deliverables. For iterative ML development, we incorporate feedback from your model training to refine guidelines and improve annotation quality over subsequent batches. The goal is continuous improvement, not one-time data delivery.

How it works

Our annotation process matches how ML development actually works: iterative, feedback-driven, and quality-sensitive.

Why choose Travod?

Subject-matter expertise

We match annotation projects with linguists who have relevant domain backgrounds. Medical annotation is handled by annotators with healthcare experience. Legal labeling goes to those who command regulatory language. Technical content is assigned to annotators familiar with engineering terminology. This expertise shows in label accuracy, especially for edge cases where domain knowledge determines the correct annotation decision.
Subject-matter expertise | Travod
Subject-matter expertise

Annotation that determines model performance